NobleProg delivers expert-led GPU training courses across Nepal, empowering professionals and organizations with the latest industry skills. Leveraging our extensive presence in the Indian subcontinent, we provide accessible and high-quality learning solutions tailored to the local market. Participants gain valuable insights through interactive sessions designed to enhance career growth and organizational performance.
Delivered either online or onsite, these instructor-led live training courses on GPU (Graphics Processing Unit) utilize interactive discussions and hands-on practice to impart the core principles of GPU technology and programming techniques.
GPU training is offered in two formats: "online live training" and "onsite live training." Online live training (also known as "remote live training") is conducted through an interactive remote desktop. Onsite live training can be provided directly at your premises in Nepal or at NobleProg corporate training centers in Nepal.
NobleProg -- Your Local Training Provider
Nepal, Kathmandu - Classroom
near Soaltee, Tahachal Marg, Kathmandu, Nepal, 44600
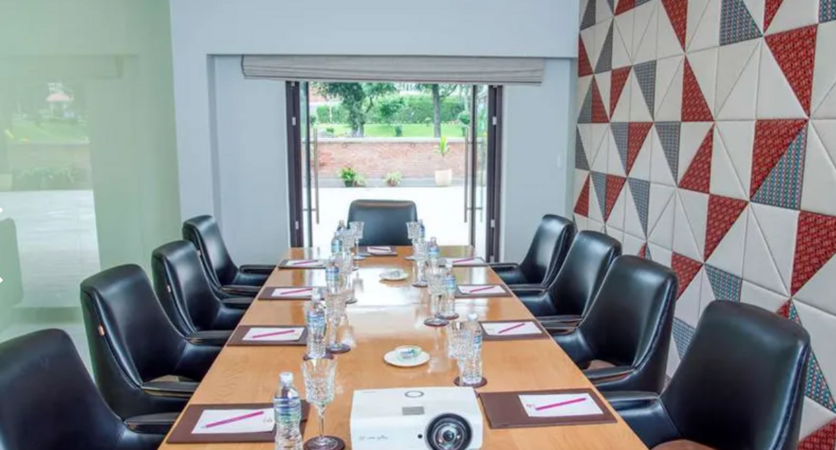
Set in Kathmandu, this classroom is well located near Tahachal Marg with all amenities and WiFi.
For Sales Enquires and Meetings
All our centres have batches running on weekdays and weekends hence, please note that, in most cases, usually we are not able to organise ad hoc sales meetings, especially on our classrooms as they are all occupied with ongoing training sessions . Please contact us by e-mail or phone at least one day earlier to make an appointment with one of our consultants at our corporate offices.
Nepal, Thamel, KTM - Classroom
near Radisson , Ward 2, Kathmandu, Nepal, 44600
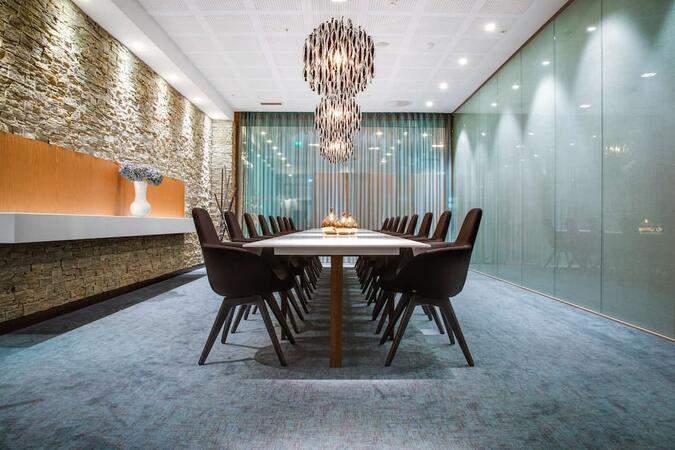
Set in Kathmandu, this classroom is well located near Thamel, with all amenities and WiFi.
For Sales Enquires and Meetings
All our centres have batches running on weekdays and weekends hence, please note that, in most cases, usually we are not able to organise ad hoc sales meetings, especially on our classrooms as they are all occupied with ongoing training sessions . Please contact us by e-mail or phone at least one day earlier to make an appointment with one of our consultants at our corporate offices.
This live, instructor-led course in Nepal empowers intermediate AI engineers to construct and refine neural network models via the Huawei Ascend platform and CANN toolkit. Learners will configure environments, develop applications using MindSpore, and deploy solutions to edge or cloud environments.
This instructor-led live training in Nepal delves into Huawei's AI stack, ranging from the CANN SDK to the MindSpore framework. It empowers beginners and intermediate professionals to grasp how these components integrate on Ascend hardware, enhancing lifecycle management and deployment strategies.
This instructor-led, live training in Nepal (online or onsite) targets beginner to intermediate developers who wish to utilize OpenACC to program heterogeneous devices and exploit their parallelism.
By the end of this training, participants will be able to:
Set up an OpenACC development environment.
Write and run a basic OpenACC program.
Annotate code with OpenACC directives and clauses.
This instructor-led training on Nepal focuses on deploying and optimizing CV and NLP models using the CANN SDK for Ascend hardware. Learners will master model conversion, live pipeline integration, and enhancing inference performance for real-time detection and analysis.
This instructor-led live training in Nepal (online or onsite) targets beginner to intermediate developers keen on learning the fundamentals of GPU programming and the key frameworks and tools for developing GPU applications.
Upon completing this training, participants will be able to: Understand the differences between CPU and GPU computing, including the benefits and challenges of GPU programming.
Choose the right framework and tool for their GPU application.
Create a basic GPU program that performs vector addition using one or more of the frameworks and tools.
Use the respective APIs, languages, and libraries to query device information, allocate and deallocate device memory, copy data between host and device, launch kernels, and synchronize threads.
Use the respective memory spaces, such as global, local, constant, and private, to optimize data transfers and memory accesses.
Use the respective execution models, such as work-items, work-groups, threads, blocks, and grids, to control the parallelism.
Debug and test GPU programs using tools such as CodeXL, CUDA-GDB, CUDA-MEMCHECK, and NVIDIA Nsight.
Optimize GPU programs using techniques such as coalescing, caching, prefetching, and profiling.
This live, instructor-led training in Nepal empowers advanced developers with the proficiency required to construct, deploy, and tune custom AI operators. Participants will gain mastery over CANN TIK and Apache TVM integration, enabling sophisticated optimisation and scheduling on Huawei Ascend hardware for real-world performance gains.
This instructor-led, live training in Nepal (online or onsite) targets beginner to intermediate developers who want to utilise diverse frameworks for GPU programming and compare their features, performance, and compatibility.
Upon completing this training, participants will be able to:
Set up a development environment featuring the OpenCL SDK, CUDA Toolkit, ROCm Platform, a device supporting OpenCL, CUDA, or ROCm, and Visual Studio Code.
Develop a basic GPU program performing vector addition using OpenCL, CUDA, and ROCm, and compare the syntax, structure, and execution of each framework.
Employ the respective APIs to query device information, allocate and deallocate device memory, copy data between host and device, launch kernels, and synchronize threads.
Utilise the respective languages to write kernels that execute on the device and manipulate data.
Use the respective built-in functions, variables, and libraries to carry out common tasks and operations.
Leverage the respective memory spaces, such as global, local, constant, and private, to optimise data transfers and memory accesses.
Apply the respective execution models to manage the threads, blocks, and grids that define parallelism.
Debug and test GPU programs using tools like CodeXL, CUDA-GDB, CUDA-MEMCHECK, and NVIDIA Nsight.
Optimise GPU programs employing techniques such as coalescing, caching, prefetching, and profiling.
This instructor-led training in Nepal presents CloudMatrix as a solution for scalable AI inference. Discover how to deploy, optimize, and oversee models using CANN and MindSpore. Practical exercises address packaging, conversion, serving, and performance tuning for both real-time and batch workloads.
This live, instructor-led training in Nepal explores the fundamental principles and practical aspects of deploying AI models on Ascend edge devices using the CANN toolkit, enabling participants to develop competencies in compiling, optimizing, and managing resource-limited environments.
This instructor-led, live training in Nepal (online or onsite) is aimed at beginner-level to intermediate-level developers who wish to install and use ROCm on Windows to program AMD GPUs and exploit their parallelism.
By the end of this training, participants will be able to:
Set up a development environment that includes ROCm Platform, a AMD GPU, and Visual Studio Code on Windows.
Create a basic ROCm program that performs vector addition on the GPU and retrieves the results from the GPU memory.
Use ROCm API to query device information, allocate and deallocate device memory, copy data between host and device, launch kernels, and synchronize threads.
Use HIP language to write kernels that execute on the GPU and manipulate data.
Use HIP built-in functions, variables, and libraries to perform common tasks and operations.
Use ROCm and HIP memory spaces, such as global, shared, constant, and local, to optimize data transfers and memory accesses.
Use ROCm and HIP execution models to control the threads, blocks, and grids that define the parallelism.
Debug and test ROCm and HIP programs using tools such as ROCm Debugger and ROCm Profiler.
Optimize ROCm and HIP programs using techniques such as coalescing, caching, prefetching, and profiling.
This instructor-led, live training in Nepal (online or onsite) is aimed at beginner-level to intermediate-level developers who wish to use ROCm and HIP to program AMD GPUs and exploit their parallelism.
By the end of this training, participants will be able to:
Set up a development environment that includes ROCm Platform, an AMD GPU, and Visual Studio Code.
Create a basic ROCm program that performs vector addition on the GPU and retrieves the results from the GPU memory.
Use ROCm API to query device information, allocate and deallocate device memory, copy data between host and device, launch kernels, and synchronize threads.
Use HIP language to write kernels that execute on the GPU and manipulate data.
Use HIP built-in functions, variables, and libraries to perform common tasks and operations.
Use ROCm and HIP memory spaces, such as global, shared, constant, and local, to optimize data transfers and memory accesses.
Use ROCm and HIP execution models to control the threads, blocks, and grids that define the parallelism.
Debug and test ROCm and HIP programs using tools such as ROCm Debugger and ROCm Profiler.
Optimize ROCm and HIP programs using techniques such as coalescing, caching, prefetching, and profiling.
This live training in Nepal presents the CANN toolkit to AI framework developers. It guides you through setting up environments, converting models, and deploying applications on Ascend hardware using MindSpore, TensorFlow, or PyTorch, addressing the complete workflow from training to inference.
Enhance AI workload efficiency on Ascend, Biren, and Cambricon through this hands-on training in Nepal. Master the art of model benchmarking, bottleneck identification, and the application of graph, kernel, and operator-level optimizations. Fine-tune deployment pipelines to boost throughput and minimize latency across these top-tier platforms.
Maximize neural network inference efficiency on Ascend AI processors through this advanced, instructor-led course in Nepal. Dive into CANN's runtime architecture, utilizing the Graph Engine, TIK, and TVM to master profiling, develop custom operators, and resolve memory bottlenecks.
Transition CUDA applications to Chinese GPU architectures such as Huawei Ascend and Biren in Nepal. This live course guides advanced programmers through code translation and performance optimization, featuring hands-on labs for porting CUDA codebases to new SDKs.
This instructor-led, live training in Nepal (online or onsite) is aimed at beginner-level to intermediate-level developers who wish to use CUDA to program NVIDIA GPUs and exploit their parallelism.
By the end of this training, participants will be able to:
Set up a development environment that includes CUDA Toolkit, an NVIDIA GPU, and Visual Studio Code.
Create a basic CUDA program that performs vector addition on the GPU and retrieves the results from the GPU memory.
Use the CUDA API to query device information, allocate and deallocate device memory, copy data between host and device, launch kernels, and synchronize threads.
Use the CUDA C/C++ language to write kernels that execute on the GPU and manipulate data.
Use CUDA built-in functions, variables, and libraries to perform common tasks and operations.
Use CUDA memory spaces, such as global, shared, constant, and local, to optimize data transfers and memory accesses.
Use the CUDA execution model to control the threads, blocks, and grids that define the parallelism.
Debug and test CUDA programs using tools such as CUDA-GDB, CUDA-MEMCHECK, and NVIDIA Nsight.
Optimize CUDA programs using techniques such as coalescing, caching, prefetching, and profiling.
This live training in Nepal equips intermediate AI developers with the expertise to deploy models on Ascend processors using the CANN toolkit. Participants will learn to convert models from frameworks like PyTorch and TensorFlow, optimize performance, and troubleshoot issues to ensure efficient edge and cloud inference.
This live training in Nepal empowers developers with the expertise to program and optimize applications on Biren AI accelerators. Participants will gain insights into GPU architecture, learn to configure the SDK, and translate CUDA code for Biren. The course places significant emphasis on performance tuning and debugging strategies.
This live, instructor-led training on Nepal empowers developers to construct and deploy AI models using BANGPy and Neuware on Cambricon MLUs. Learners will configure their environments, develop highly optimized models, and integrate MLU acceleration into edge and data center applications.
This instructor-led, live training in Nepal (online or onsite) is designed for beginner-level system administrators and IT professionals who wish to install, configure, manage, and troubleshoot CUDA environments.
Upon completing this training, participants will be able to:
Comprehend the architecture, components, and capabilities of CUDA.
This instructor-led, live training in Nepal (online or onsite) is designed for beginner to intermediate-level developers who want to use OpenCL to program heterogeneous devices and leverage their parallelism.
Upon completion of this training, participants will be able to:
Set up a development environment comprising the OpenCL SDK, an OpenCL-compatible device, and Visual Studio Code.
Develop a fundamental OpenCL program that performs vector addition on the device and retrieves results from device memory.
Utilize the OpenCL API to query device information, and create contexts, command queues, buffers, kernels, and events.
Write kernels using the OpenCL C language to execute on the device and manipulate data.
Employ OpenCL built-in functions, extensions, and libraries to carry out common tasks and operations.
Leverage OpenCL host and device memory models to optimize data transfers and memory access.
Use the OpenCL execution model to manage work-items, work-groups, and ND-ranges.
Debug and test OpenCL programs using tools like CodeXL, Intel VTune, and NVIDIA Nsight.
Optimize OpenCL programs through techniques such as vectorization, loop unrolling, local memory usage, and profiling.
This instructor-led, live training in Nepal (online or onsite) is designed for C++ developers who intend to use CUDA to expedite applications, develop high-performance GPU kernels, and exploit parallel algorithm libraries for scientific computing, data processing, and machine learning tasks.
This instructor-led, live training in Nepal (online or onsite) is designed for C/C++ developers who wish to utilize CUDA to accelerate compute-intensive applications, including data processing, scientific simulations, machine learning workloads, and image processing pipelines.
This instructor-led, live training in Nepal (online or onsite) targets software developers, data analysts, and technical professionals who want to use TensorFlow 2.x and Keras to build, train, and deploy deep learning models for computer vision, natural language processing, and multimodal applications.
This instructor-led, live training programme conducted in Nepal explores GPU programming for parallel computing, the use of various platforms, hands-on work with CUDA features, and optimization strategies using CUDA. Relevant applications include deep learning, analytics, image processing, and engineering use cases.
Read more...
Last Updated:
Testimonials (1)
Trainers energy and humor.
Tadeusz Kaluba - Nokia Solutions and Networks Sp. z o.o.
Online GPU (Graphics Processing Unit) training in Nepal, Graphics Processing Unit training courses in Nepal, Weekend Graphics Processing Unit courses in Nepal, Evening GPU training in Nepal, GPU instructor-led in Nepal, Evening GPU courses in Nepal, GPU (Graphics Processing Unit) instructor in Nepal, Graphics Processing Unit classes in Nepal, Graphics Processing Unit boot camp in Nepal, GPU (Graphics Processing Unit) instructor-led in Nepal, GPU private courses in Nepal, Weekend GPU (Graphics Processing Unit) training in Nepal, Online GPU (Graphics Processing Unit) training in Nepal, GPU (Graphics Processing Unit) coaching in Nepal, Graphics Processing Unit on-site in Nepal, Graphics Processing Unit trainer in Nepal, GPU (Graphics Processing Unit) one on one training in Nepal